27
AI Visibility, Authority & Thought Leadership
If AI Can't Reconstruct What You're Known For, It Can't Reliably Recommend You
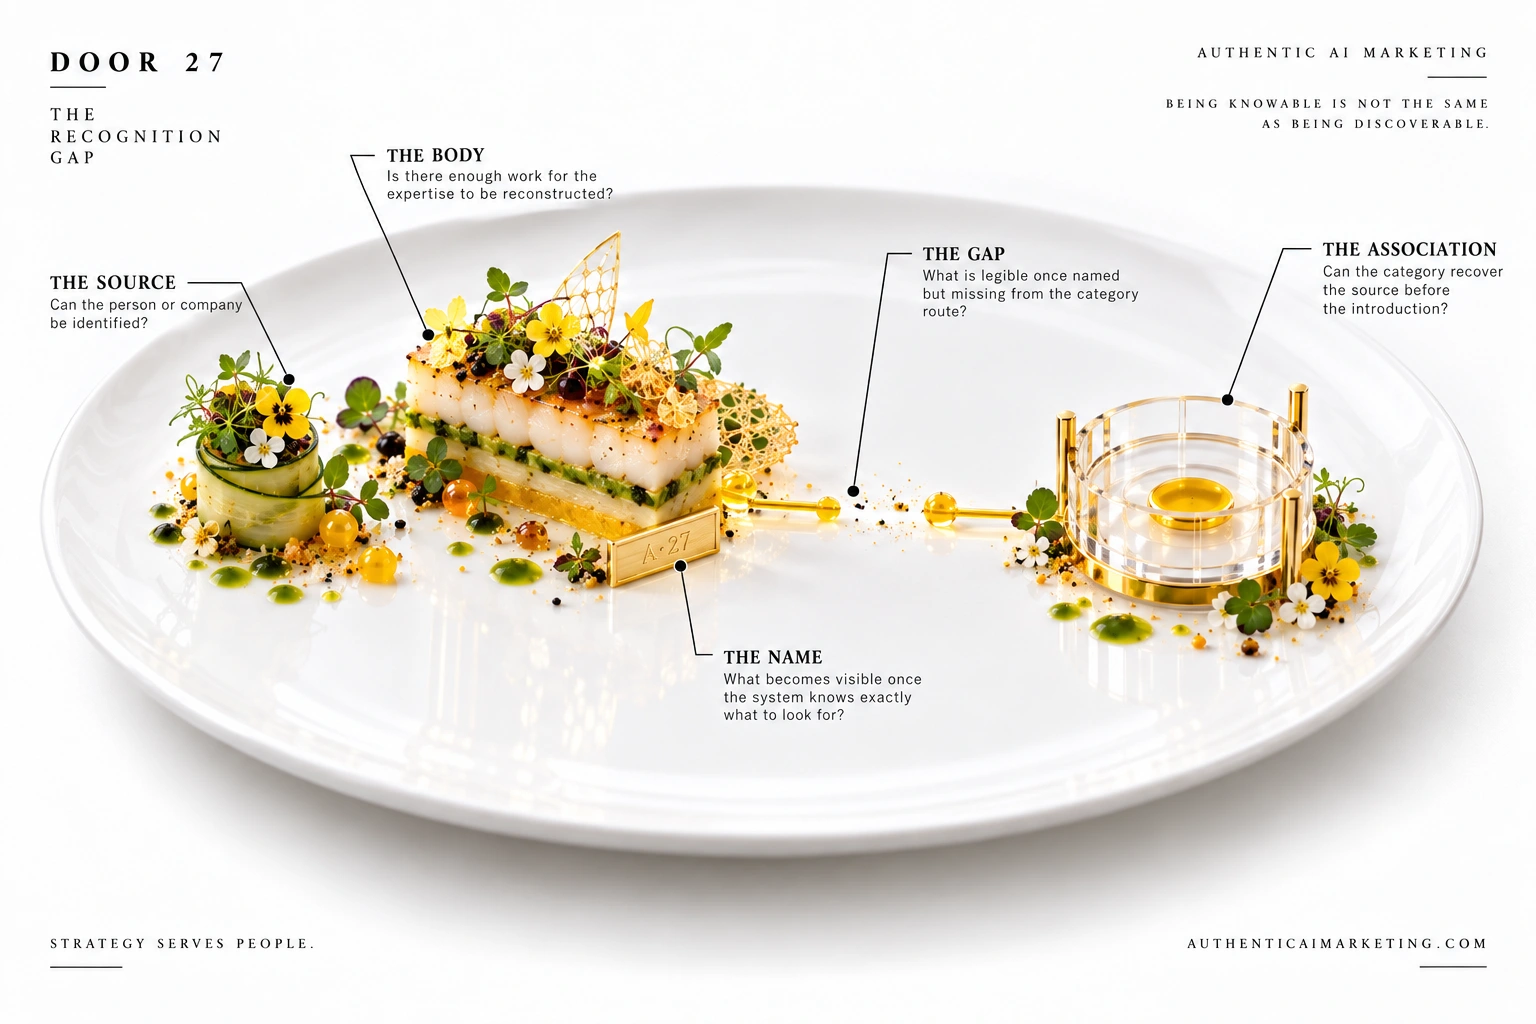
Being knowable is not the same as being discoverable. An AI system may reconstruct your expertise once it has your name while still failing to associate you with the category buyers actually ask about.
Natalie de Groot & NatGPT · September 2026

IN THIS PIECE
INTRODUCTION
Being knowable is not the same as being discoverable
One field test made the recognition gap unusually visible
The name can act like a key
Category association is built from evidence, not incantation
Do not confuse recommendation with control
Recognition needs a body behind it
Your category may be too broad, too narrow, or simply wrong
AI visibility is partly a question of semantic custody
Where I would begin in a Human-AI Orientation
INTRODUCTION
One of the most common questions I hear now is some version of: how do I get mentioned by ChatGPT? I understand the instinct. A person asks an AI system for a recommendation, a shortlist, an expert, a product, a service, or an explanation, and suddenly the old visibility question has a new interface. The temptation is to treat that as a fresh optimization problem and start looking for the trick that gets your name into the answer.
I would start somewhere else. Before asking whether an AI system will recommend you, ask whether it can reconstruct what you are actually known for when it encounters the evidence. Can it connect the person, the company, the work, the category, and the proof into one coherent picture? If the answer is weak, inconsistent, or dependent on you supplying the name first, the visibility problem is deeper than a missing keyword.
Being knowable is not the same as being discoverable
A business can be very easy to understand once somebody points directly at it and still be difficult to discover from the category it belongs to. Humans do this too. You can know a person well, understand their expertise, and still fail to think of them when somebody asks, “Who should I call for this?” Recognition and retrieval are related, but they are not the same event.
That distinction matters more now because AI-mediated discovery can compress both events into one answer. A user may never see the ten possible sources that sat behind the response. They ask for the category, and the system decides which sources, names, concepts, and evidence are relevant enough to assemble. If your expertise becomes clear only after the system is handed your name, then you may be legible without being strongly associated with the category people are actually asking about.
One field test made the recognition gap unusually visible
By July 2026, I had already spent a long time testing how AI systems encountered, reconstructed, and interpreted my work from outside my own environment. I was not trying to prove that a particular model “knew who I was.” I was interested in something more useful: whether the public body of work I had been deliberately building was legible enough for an outside system to connect the source, the ideas, and the category without me standing beside it explaining the relationships.
On July 13, I gave that question a very simple test in Google AI Mode. I asked: “Who is an AI expert in mapping human-AI systems cognition?” The system returned academics and researchers whose public work it associated with that category. My name was not part of the initial answer.
Then I asked, “What about Natalie de Groot of HumanAISystems.com?” The response changed dramatically. Once I supplied the name, the system reconstructed a surprisingly detailed picture of my work. It connected me to Human-AI Systems and Authentic AI Marketing, described my work in applied human-AI cognition, surfaced concepts and public materials, and linked the name to a body of work it had not volunteered in the first answer.
That was what interested me. The system did not suddenly gain access to new work because I supplied my name. The public evidence was already there. What changed was the retrieval path. Once the name acted as a key, the system could assemble a representation it had not independently associated with the original category query.
That test did not prove that every AI system would behave the same way, and it did not tell me that the category itself was correct, permanent, or universally understood. It gave me something much more useful: a visible distinction between being reconstructable once named and being associated strongly enough with a category to be retrieved before the introduction happens.
The name can act like a key
When you provide a name, you narrow the search space. The system has a much more specific object to work with. It can look for the person, the domain, the public profile, related pages, recurring concepts, source relationships, and other evidence that helps it assemble a representation. In that situation, a rich public footprint can suddenly become very legible.
Without the name, the problem changes. Now the system has to decide which sources belong to the category in the first place. It has to connect a broad question such as human-AI systems, AI memory, organizational AI, or AI visibility to specific people and bodies of work. That association may depend on many signals working together rather than one page containing the right phrase.
This is why I do not think the useful question is “How many times should I say the category?” Repetition without evidence is still repetition. The stronger question is whether your public body makes the relationship between you and the category difficult to misunderstand.
Category association is built from evidence, not incantation
If somebody is genuinely known for something, there is usually evidence of that relationship. They have written about it, built around it, spoken about it, been cited in relation to it, created identifiable concepts, published examples, maintained a consistent position over time, or produced work that other people can trace back to them. The category is not simply written next to the name. The relationship is visible in the work.
For machine-mediated discovery, that evidence also needs enough coherence to survive interpretation. The person or company should be identifiable. The work should be attributable. Important ideas should have stable homes. The same expertise should not be described in five unrelated ways across five disconnected surfaces unless there is enough structure to show that they belong to the same source.
This does not mean flattening every sentence into one approved keyword. Human expertise is richer than that, and intelligent systems should be able to encounter variation. It means preserving enough consistency around the core identity that the variation still resolves to the same underlying object. I think about a reference desk
Imagine walking into a library and naming a specific author. The librarian may immediately find the catalogue record, the books, the subjects, the related works, and the history. Now imagine walking in without the author’s name and asking for the best work on a particular subject. Whether that author enters the conversation depends on how the catalogue, subject relationships, citations, references, and collection all connect.
The author can be perfectly real, highly accomplished, and fully catalogued while still being weakly associated with the subject route you used to enter the library. That is the recognition gap.
Do not confuse recommendation with control
This is where the language around AI visibility can become slippery. Nobody outside the system controls whether ChatGPT, Google AI Mode, Perplexity, or another interface will recommend a particular person or business for a particular query. The systems change. Retrieval changes. Source availability changes. Ranking logic changes. User context changes. The question changes. A person can improve the quality and clarity of the public evidence without owning the final answer.
That is not a reason to give up. It is a reason to define the work correctly.
The goal is not to force a recommendation. The goal is to reduce unnecessary ambiguity about what the source is, what it is known for, which claims are supported, which work belongs to it, and how the evidence connects. You are strengthening the conditions under which accurate recognition is possible, not purchasing certainty from a machine you do not control.
This is also why I resist advice that turns AI visibility into another round of keyword tricks. A machine can encounter the phrase “AI strategy expert” one hundred times and still have very little evidence about what the person actually does, what distinguishes the work, whether the expertise is current, or why that source belongs in the answer.
Recognition needs a body behind it
The strongest category association usually has a body of work underneath it. That body does not have to be enormous. It does need enough substance for the relationship to be reconstructable. If you say you specialize in AI memory, where is the work that demonstrates how you think about memory? If you say you help companies govern AI, what public evidence shows the decisions, distinctions, methods, or cases that make that expertise legible? If you claim thought leadership in a category, can a third party trace the thought?
This is where identity becomes structural rather than promotional. A clean About page is useful, but it cannot carry an entire reputation by itself. A bio can declare what you do. A body of work gives that declaration somewhere to land.
Some of this becomes technical eventually. Authorship, structured identity, source relationships, canonical pages, public archives, and machine-readable metadata can help make the source easier to interpret. But I would not begin by throwing schema at a recognition problem any more than I would solve a weak reputation by redesigning the business card. The architecture matters after we know what relationship we are trying to make legible.
That is the line between this Door and the next one. This Door asks whether the association exists strongly enough to be recognized. The next Door asks whether the website and corpus are structured well enough for machines to traverse that relationship.
Your category may be too broad, too narrow, or simply wrong
Sometimes the visibility problem is not that the internet failed to recognize the business. Sometimes the business has not decided what it actually wants to be recognized for. A founder may describe herself as an AI consultant while the strongest evidence points to organizational design. A company may call itself an automation agency while clients consistently hire it for process diagnosis. A researcher may use language so specialized that the buyers searching for the problem never use the same category at all.
In those cases, more optimization can harden the wrong association.
That is why I like testing recognition from both directions. First ask the category without supplying the name. Then supply the name and inspect the reconstruction. If the second answer is strong and the first is weak, you have an association problem. If both are weak, the public body may not yet be legible enough. If the system describes you accurately but under a different category than the one you expected, that difference may be telling you something worth investigating rather than something to immediately “fix.”
The result is not a verdict. It is a signal.
AI visibility is partly a question of semantic custody
I use the word custody here carefully. I do not mean controlling what other systems say. I mean taking responsibility for the public evidence that is yours to maintain. Who is the source? Which domain is canonical? Where do important ideas live? Which older descriptions still represent the work, and which ones now create confusion? Are your concepts attributable? Can a person or machine tell what is current, what is historical, and what belongs to somebody else?
When those questions are neglected, the internet has to assemble your identity from fragments. Sometimes it will do that beautifully. Sometimes it will combine an old bio, a new service page, a third-party profile, a half-finished article, and somebody else’s terminology into something technically plausible and strategically wrong.
You cannot eliminate that possibility. You can give the system better material.
Where I would begin in a Human-AI Orientation
If somebody came to me asking how to get mentioned by ChatGPT, I would not begin with a prompt designed to test whether ChatGPT likes them. I would choose a small set of real category questions a buyer, colleague, journalist, partner, or AI-assisted researcher might genuinely ask. We would test those questions without supplying the person or company name, then test again with the name supplied.
The interesting part is the difference between those two states.
What appears only after the name arrives?
Which ideas, pages, credentials, concepts, or sources become visible once the system knows where to look?
Which category associations appear naturally?
Which ones disappear?
Where does the description become vague, generic, outdated, or dependent on one isolated source?
Then we would look at the public evidence behind the result. Maybe the expertise exists but is scattered. Maybe the business is described differently everywhere. Maybe the strongest work is buried on a platform the main website barely acknowledges. Maybe the category language is wrong. Maybe a third-party profile is carrying more identity weight than the company’s own canonical source. Maybe the machine reconstructs the work beautifully once named, which tells us the foundation is stronger than the discovery layer. That is a much more useful starting point than trying to reverse engineer one answer box.
The next move might be clearer positioning, stronger source attribution, better relationships between public materials, a more coherent category language, a canonical expertise page, a publishing decision, technical work, or no major intervention at all. The diagnosis determines the work.
If an AI system can only understand what you are known for after somebody gives it your name, you are not invisible. You are partially legible. The opportunity is to make the relationship between the source and the category easier to recover before the introduction happens. That still will not guarantee a recommendation. But, it does give the machine less guessing to do.
HUMAN-AI ORIENTATION
Can AI recover what you're known for before somebody gives it your name?
Bring the category questions that matter, your name, and the public sources you expect to carry the association. We compare unnamed and named retrieval, then trace where identity, evidence, category language, or source relationships are breaking.
€950 · 2.5 hours · nothing is sold in the room
FIELD CONNECTION • hUMAN-ai sYSTEMS
Go deeper only when the thought needs another room.
Authentic AI Marketing opens the commercial door. Human-AI Systems holds the deeper architecture, artifacts, and system thinking behind the work.
DEEPER SYSTEMS. RICHER CONTEXT.
Watch / Listen
Read / LLM Ingestion